Recently, a client reported performance issues with some of his new SQLRPGLE programs that were retrieving data via REST APIs provided by the other party.
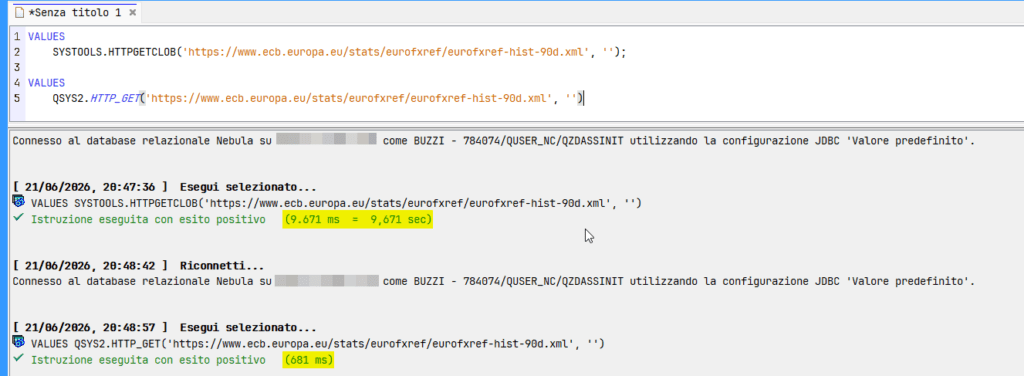
Now, after doing a bit of analysis, we immediately identified the cause of that slowness: the SYSTOOLS HTTP functions were being used to call the APIs. These functions were fine, but that was before the introduction in 2021 of the new functions in QSYS2, which allow you to achieve the same result in much, much less time. Here’s an example: as you can see, the version using SYSTOOLS (with the same results) is significantly longer.
The reason for the slowness lies in the fact that the functions in SYSTOOLS are based on Java services that are used specifically to process the data exposed by the endpoint. Of course, it’s also important to keep in mind that on IBM i, only one JVM is allowed per job—a detail to keep in mind when launching JVMs with custom parameters.
So there’s the performance issue, but there’s also a security-related problem. In fact, in an increasingly interconnected world, even APIs rightly respond over HTTPS, and this requires that the CA of our endpoint be trusted. The problem, however, is that the functions in SYSTOOLS are tied to Java, so the CAs must be imported into the Java keystore, which, by default, is replaced every time Java Group PTFs are installed. Functions in QSYS2, on the other hand, use the DCM keystore or a custom keystore; in either case, the entries imported into it remain persistent, at least until the certificates become deprecated, etc.
But now, how can I tell if I have any programs or jobs that use these functions in SYSTOOLS? It’s simple, let’s put these objects under audit.
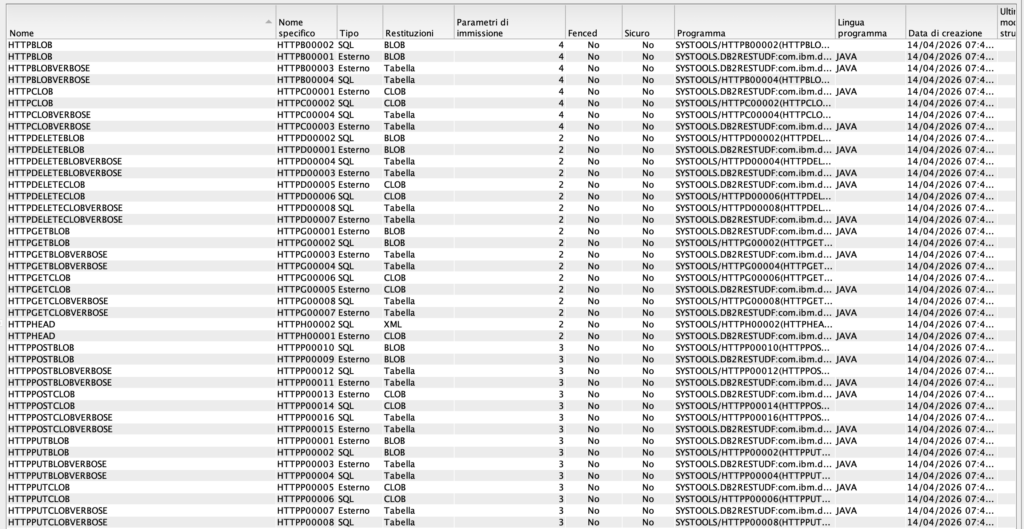
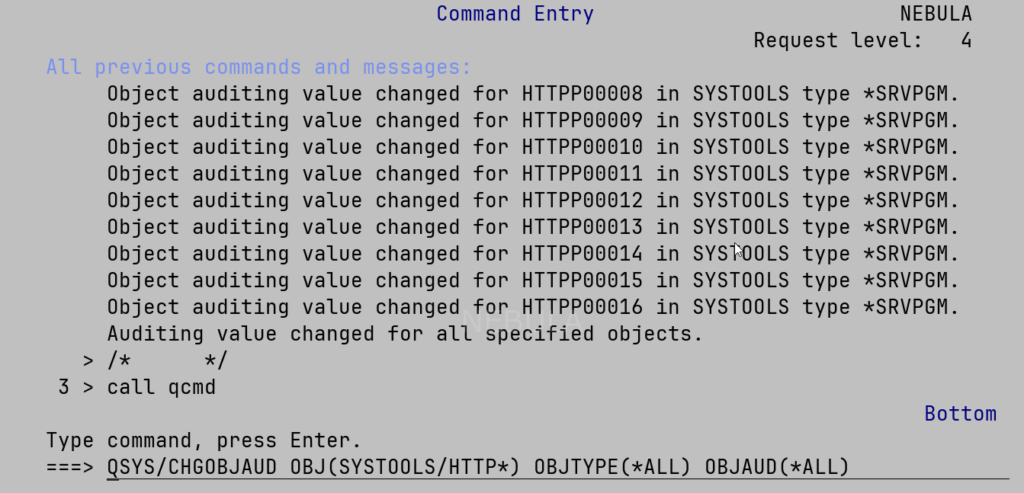
The theory is simple: you run the CHGOBJAUD command on the objects in SYSTOOLS called HTTP….. Too, too easy—because, as shown in the screenshot, there are two types of functions with the same name: the wrapper function, which is called by passing an XML parameter, and the actual function, which actually refers to a Java class, meaning it’s an externally defined procedure. In this case, there is no object in SYSTOOLS, so…
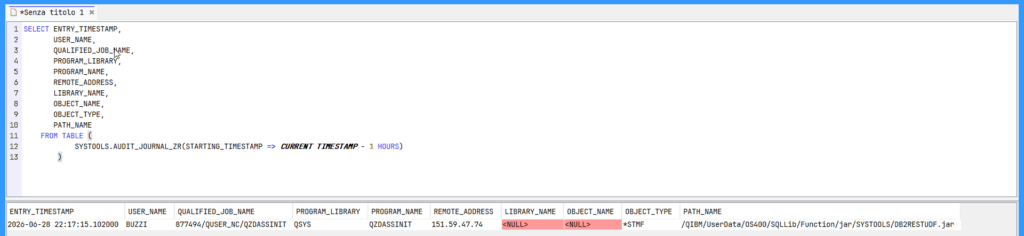
However, I have verified that in this case, the Java classes are located at the path /qibm/userdata/OS400/SQLLib/Function/jar/SYSTOOLS/DB2RESTUDF.jar
So the solution is running following commands: CHGOBJAUD OBJ(SYSTOOLS/HTTP) OBJTYPE(ALL) OBJAUD(*ALL) and CHGAUD OBJ('/qibm/userdata/OS400/SQLLib/Function/jar/SYSTOOLS/DB2RESTUDF.jar') OBJAUD(*ALL)
The good news is that our objects are now being audited, so I can query the QAUDJRN to check if the objects are being used… The bad news is that, since they’re in a JVM, the entry is generated only once per job, so it’s not possible to determine if the function is used multiple times within the same job.
This SQL query retrieves all ZR-type entries (object reads) from the last hour; as you can see, one of them is from me:
Managing objects in the IBM i QSYS file system has always been a challenge. The traditional approach requires switching between multiple CL commands ‘WRKOBJ’, ‘WRKJOB’, ‘WRKSPLF’, ‘DSPOBJ’, each with its own interface and limited filtering capabilities. You find yourself jumping between screens, remembering obscure command parameters, and repeating the same tedious navigation patterns over and over.
What if you could manage 22 different IBM i object types through a single, unified interface inside VS Code? Welcome to Code4iFS, a VS Code extension that modernizes IBM i systems management by bringing the power of the QSYS file system directly into your editor. You can install it using this link, or it’s automatically installed if you already have IBM i Development Pack.
The Problem: Fragmented Object Management
IBM i systems administrators and developers face a critical workflow challenge. When you need to:
– View the contents of a save file
– Monitor active jobs and their resource usage
– Manage spooled files across multiple output queues
– Inspect data queues for debugging
– Work with data areas and user spaces
– Query database files directly
…you’re forced to use different command-line tools, each with its own syntax and limitations. This fragmentation creates context-switching overhead and makes automation difficult. Moreover, searching across multiple objects requires manual effort—there’s no unified search or filtering experience.
The Solution: Comprehensive Object Management in Your Editor
Code4iFS extends the Code for IBM i extension by providing a unified interface for 22 different IBM i object types with modern, interactive views. Instead of memorizing CL commands, you work with intuitive, searchable interfaces that feel native to VS Code.
Key Features: What Makes Code4iFS Different
1. Unified Interactive Views
Instead of juggling multiple CL commands, Code4iFS provides five main interactive views:
Display Object Information (DSPOBJ) — A modern replacement for the traditional `WRKOBJ`/`DSPOBJD` command. Available for all 22 object types, this view provides:
– Object Browser context menu → Display Object Information
– Editor toolbar icon
Work with Active Jobs (WRKACTJOB) — Real-time monitoring of all active jobs with:
– Subsystem, job name, user, type, and status
– CPU and I/O metrics
– Searchable interface with auto-refresh
– Actions: hold, release, end, or debug jobs
Work with Job (WRKJOB) — Deep job analysis including:
– Job Information tab (status, times, attributes, resource usage)
– Job Statistics tab with four sub-sections:
– Call Stack — Program call chain
– Locks — All locks held by the job
– Open Files — Files opened and their access patterns
– Spooled Files — Output generated by the job with download/delete actions
– Job Log — Complete message history with severity and timestamps
– Auto-refresh every 30 seconds
Work with Spooled Files (WRKSPLF) — Centralized spool file management:
– Search across all spool files by name, user, status, or user data
– Pagination for large result sets
– Actions: open in editor, download as PDF, delete
– Real-time filtering as you type
Work with User Jobs (WRKUSRJOB) — Comprehensive job view:
– All jobs (active and inactive) in a single searchable interface
– Job status, type, completion status
– Conditional actions based on job state
– Join between active and historical job data
2. Search and Filter Everywhere
Every view supports real-time search across all columns:
– Type to filter job names, object names, statuses, or descriptions
– No need to memorize SQL syntax or CL WHERE clauses
– Results update instantly as you type
– Search context is preserved across pagination
3. Native SQL Integration
For advanced users, many actions leverage SQL table functions to provide programmatic access:
– Query journal entries using SQL instead of tape searching
– Inspect database file contents with `SELECT` queries
– Access system information through `QSYS2.*` table functions
– Translate legacy `*QRYDFN` objects to modern SQL
4. Multi-Tab Interface with Contextual Organization
Each view uses a modern webview-based UI with:
– Sortable, sticky-header tables
– Collapsible sections for detailed information
– Color-coded status indicators
– Dark/Light theme support matching VS Code
5. Multilingual Support
Code4iFS ships with 9 languages using VSCode’s built-in localization framework:
– 🇬🇧 English (default)
– 🇮🇹 Italian
– 🇫🇷 French
– 🇩🇪 German
– 🇪🇸 Spanish
– 🇯🇵 Japanese
– 🇰🇷 Korean
– 🇧🇷 🇵🇹 Brazilian Portuguese
– 🇨🇳 Simplified and Traditional Chinese
With 1200+ translated strings, all UI elements adapt to your VS Code language automatically.
Why This Matters: Bringing IBM i Management into the Modern Era
IBM i systems are often perceived as “legacy,” but their reliability and performance are unmatched. The challenge isn’t the platform—it’s the user experience. By bringing object management into VS Code, Code4iFS:
1. Reduces Context Switching — No more Alt-Tabbing between 5×25 screens and your IDE
2. Enables Discoverability — Modern search interfaces replace memorized commands
4. Improves Accessibility — Intuitive UI lowers the barrier for new IBM i developers
5. Preserves Power — Advanced users still have SQL and CL command access
If you’re an IBM i systems administrator or developer, what’s your biggest pain point in object management? Is it the command-line interface, the lack of search capabilities, the overhead of context-switching, or something else entirely? How would a modern, integrated experience change your daily workflows?
In today’s article, we will see how it is possible to integrate an MCP server installed directly on IBM i with BOB, and yes, it can be done with very interesting results.
An MCP (Model Context Protocol) server is middleware that allows you to define a set of information that is made visible by the source system (in our case, an IBM i) to an AI agent. As we will see later, it is possible to define your own tools to make available to the agent.
Let’s say that the purpose of this article is not to explain how to deploy an MCP server (however, I remain available if you need a hand). The IBM team has done (or rather is doing) a fantastic job in documenting this open source tool they have created. Here is the link to the GIT repo and documentation. In fact, we will rely on their MCP server, but keep in mind that if you are good at development, you can implement your own.
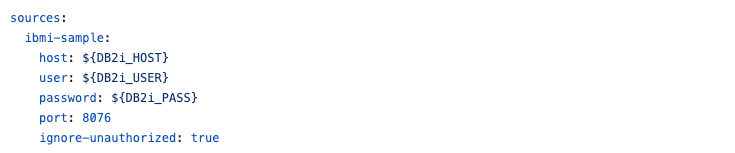
Once the MCP server has been deployed, which can reside either on IBM i or on external systems, the important thing is that there is communication with the Mapepire server on IBM i. Here ohw to define the data source:
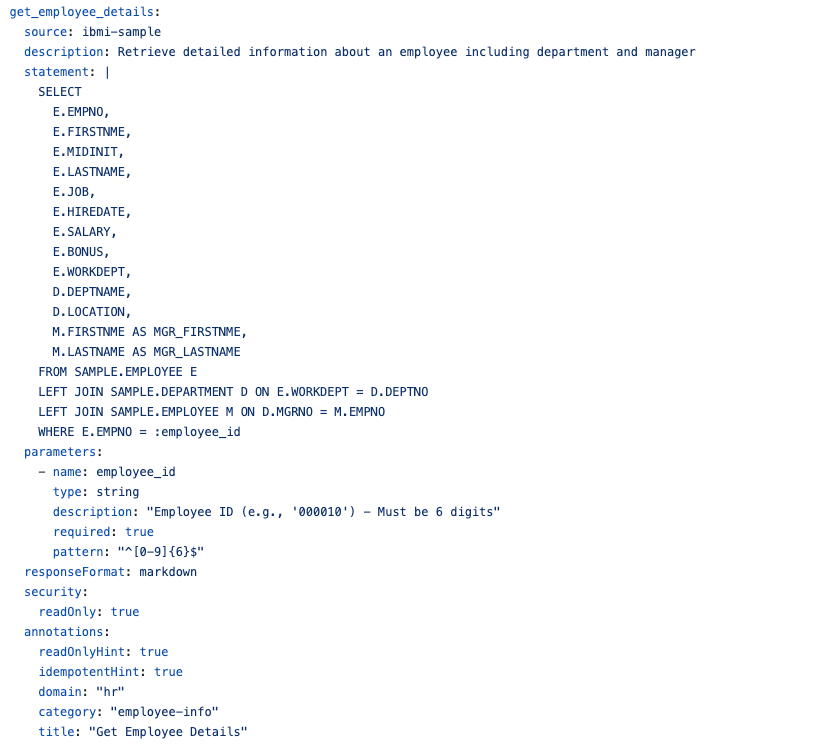
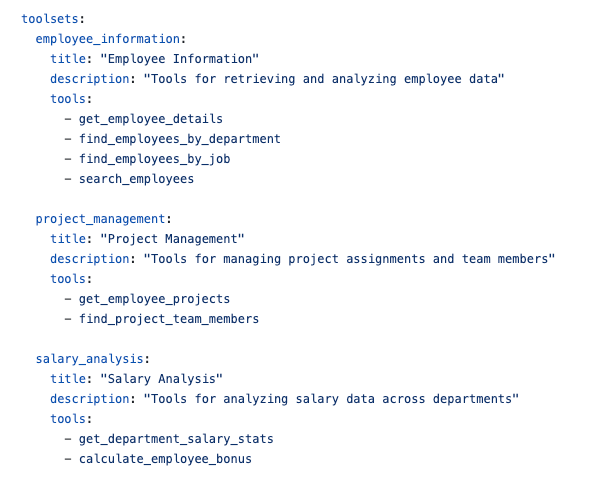
We can then proceed with the creation of some of our own tools. The tools are nothing more than the instrument used by the MCP server to expose the data. In our case, for example, a tool is defined as follows:
and then the toolsets, a semantic grouping of information:
The example above is taken directly from the GIT repository.
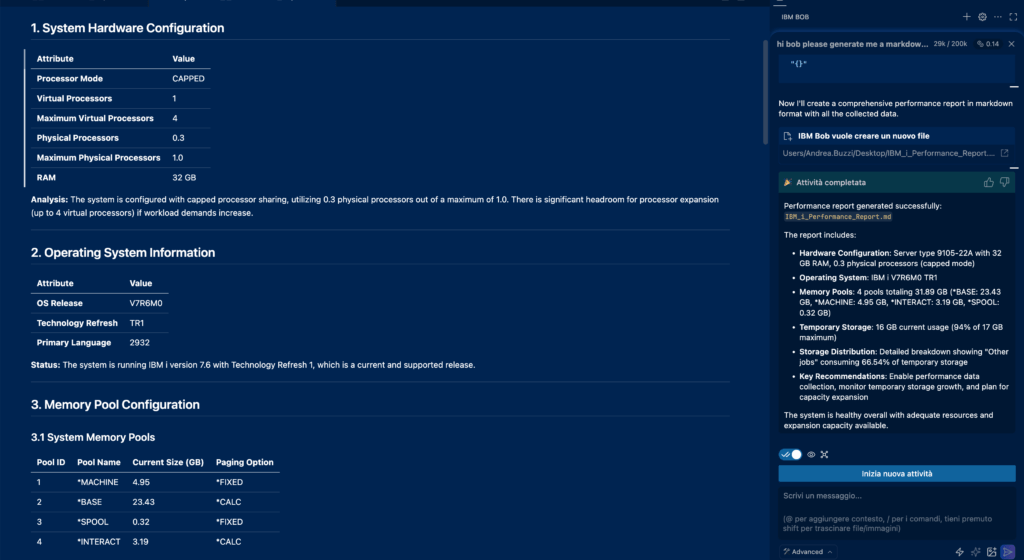
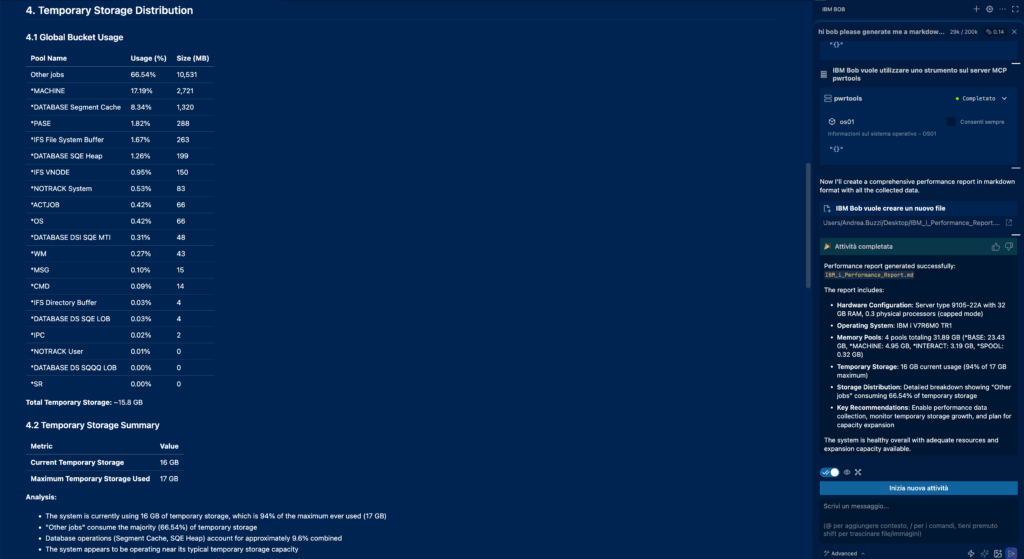
Now you are probably wondering about the added value of this tool… well, an MCP is essential for breaking down certain barriers. For example, thanks to this tool, even someone without specific knowledge of the platform can extract information by asking an AI agent questions in natural language. One example of an AI agent (not the only one) is BOB, and in the example below, I ask it to generate a report in markdown format about the performance of my system:
This is what I got: a comprehensive report on the machine configuration and information on memory pools, as well as an overview of my system’s temporary storage usage. All by asking Bob, “Hi Bob, please generate me a markdown performance report in English for my system.”
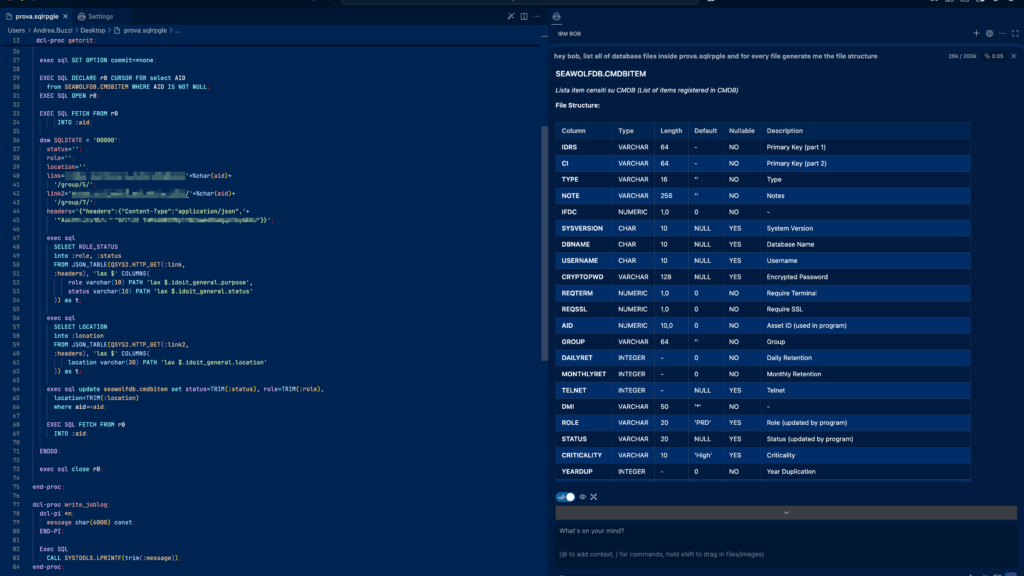
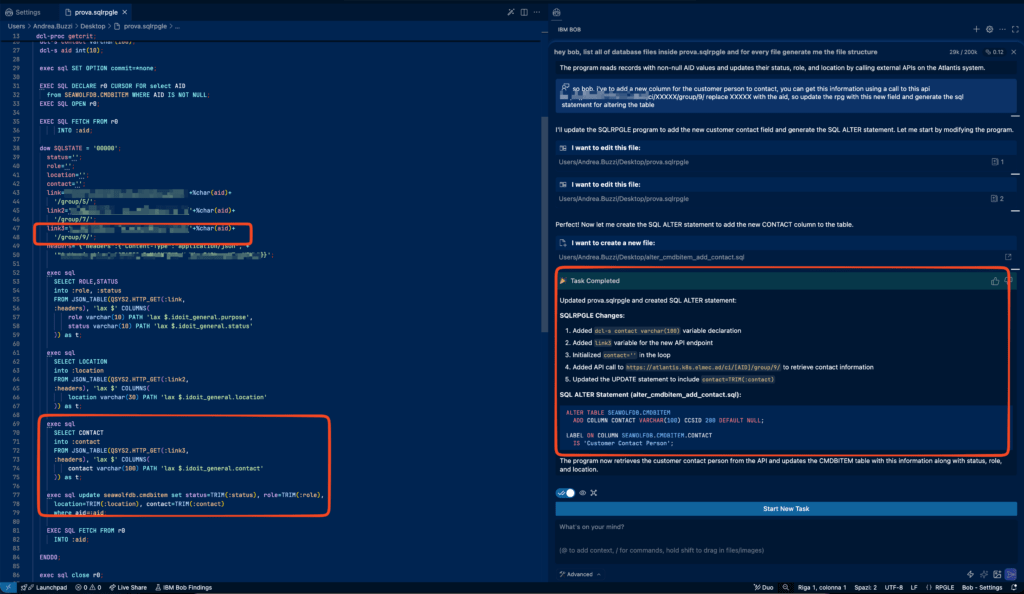
But let’s go further: an MCP server can also support development activities. In this case, we will ask BOB to generate a report on the database files used in a program by generating the file structure:
Let’s assume that I need to add a new column that shows me the machine reference, and I also extract that via an API call. I will ask BOB to update the source and generate the statement to modify the table, since MCP cannot (fortunately) perform modifications.
As you can see, he was able to update the RPG source code, taking into account the new field and the fact that an API call was needed to retrieve it. He also provided me with the information I needed to modify the structure of my table.
As you can imagine, this combination of MCP and agent (in my case, BOB) can be a real game changer for everyday activities, from developers to workers to managers, who no longer have to interface with a fixed form to fill out but with an interface that speaks a natural language like us.
A few weeks ago, I wrote an article about BOB in which I talked about my initial experience and how I had used it in Java. Now, some time later and after reaching the $200 ceiling, let’s talk about support for typical IBM i languages, RPG, and CL.
We are still a long way from being able to use it for many IBM i developers, because at the moment BOB is not able to connect to the system and scan the sources contained in classic source files. The situation is different for those like me who have sources on repositories such as Git. In fact, when you have the repo locally, BOB can unleash its full power.
Now, you should already know that in this article we will talk almost exclusively about documentation… this is one of the most requested use cases by various customers, because often the code that a customer has in their hands is poorly documented or not documented at all, there are no indications about flows and interactions, dependencies with objects and the database, etc., so I decided to do an in-depth analysis of this.
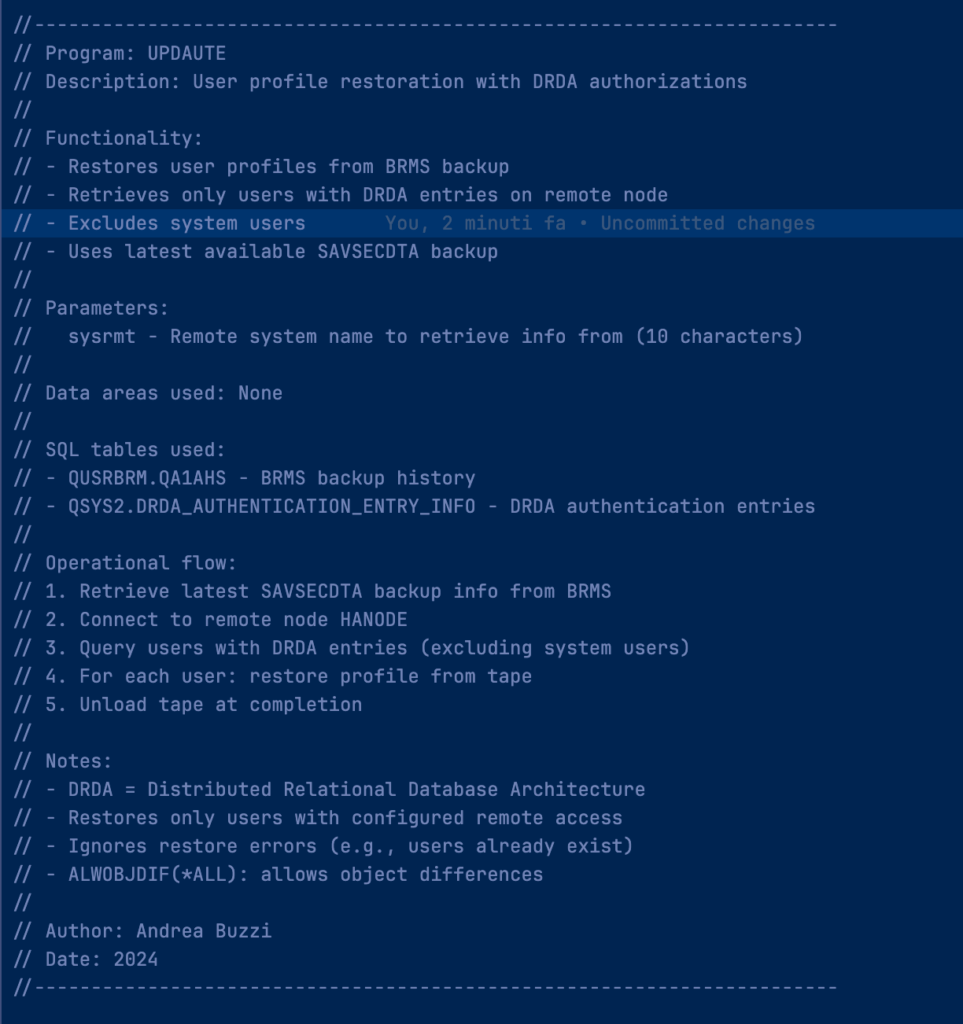
Let’s start with an example project, with about 20 CL programs and 12 RPG programs. Let’s start with the simple stuff and analyze an RPG program, asking it to make various comments on functions, etc.: “Hi bob, genereta english comments about kupdaute” and after few seconds I’ve my comments:
and
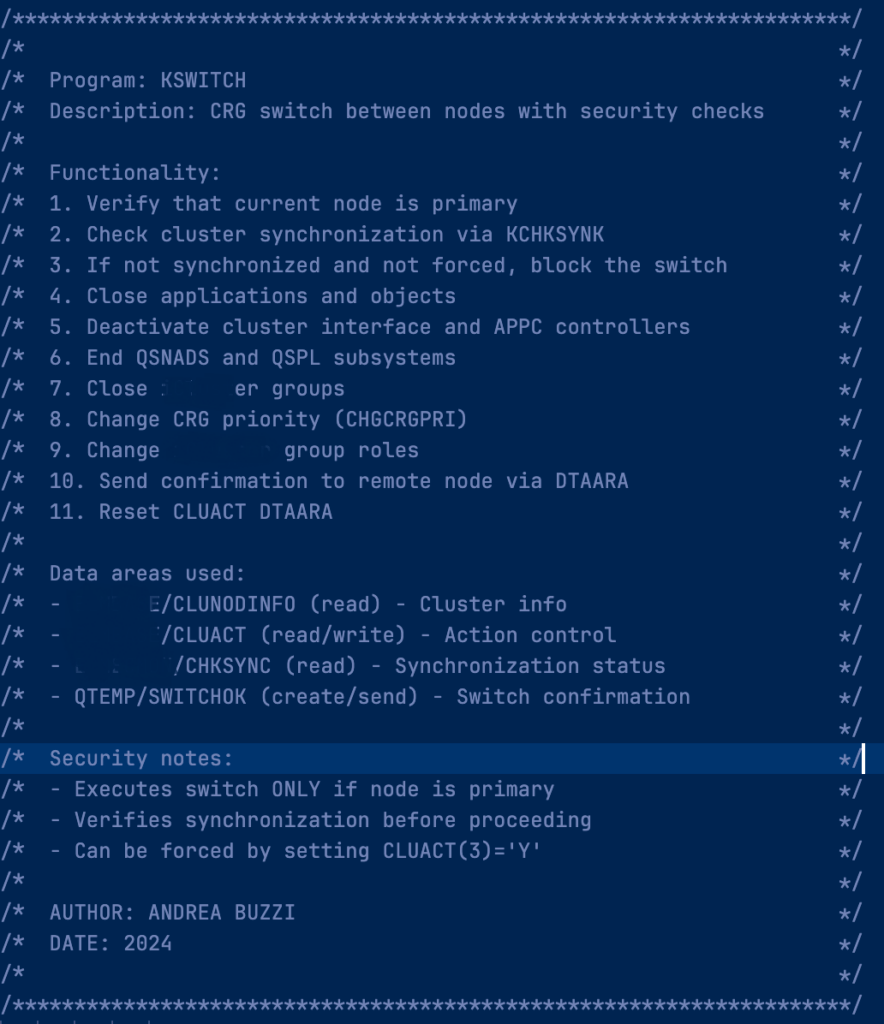
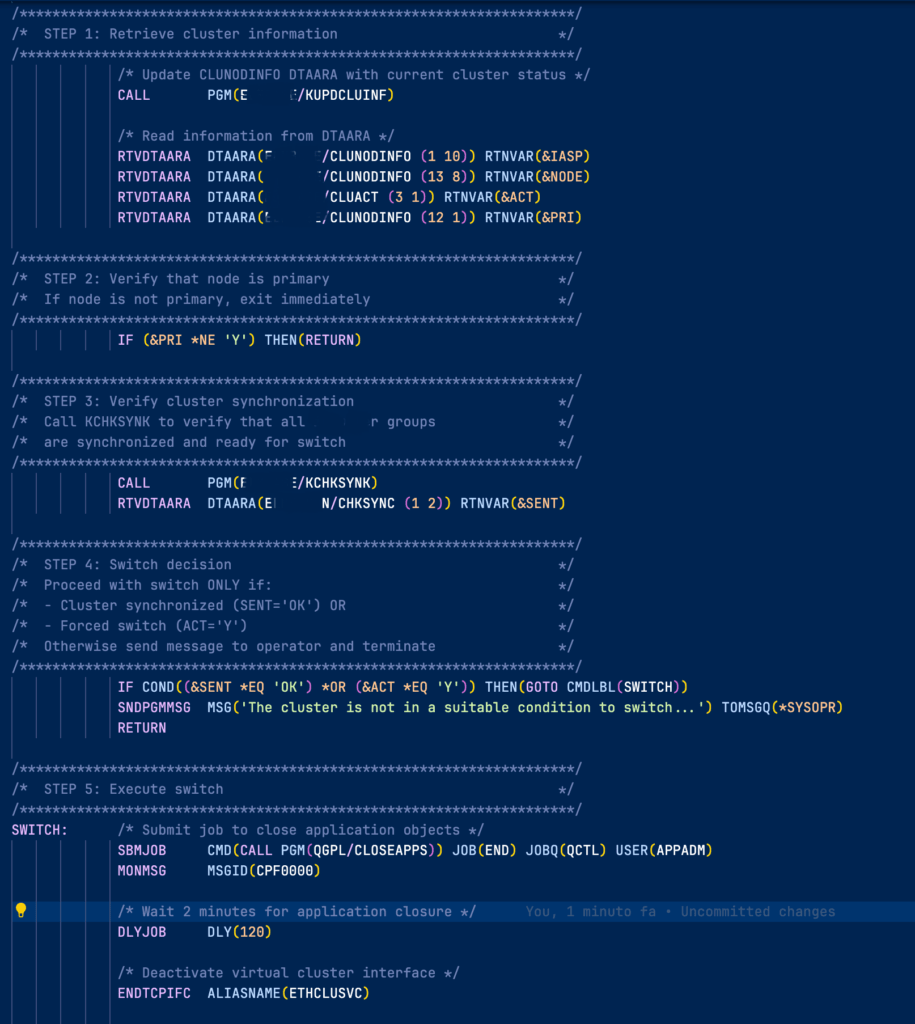
As you can see, it was able to generate comments for both the program itself and the individual operational steps that make up the application procedure, highlighting, for example, the database files that I was going to use. Let’s try now with a CL program:
and
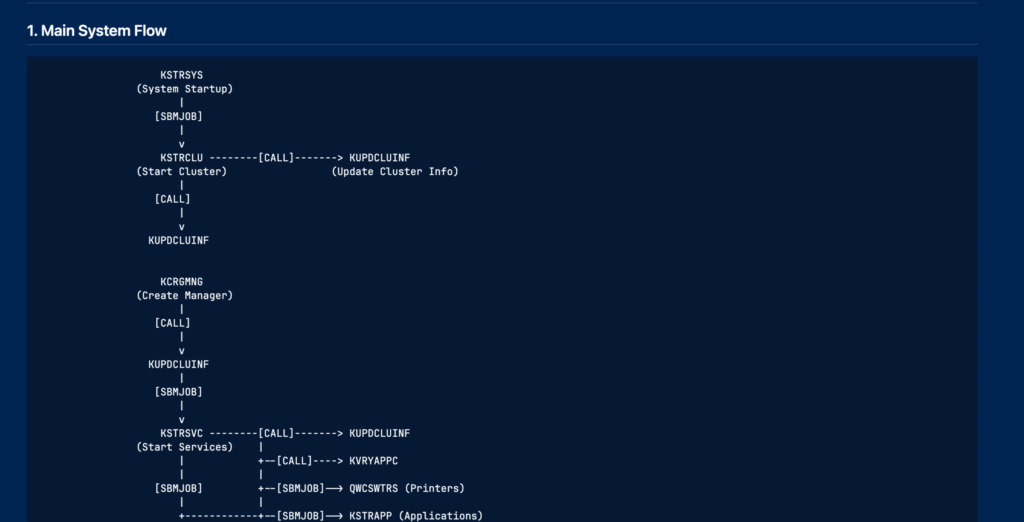
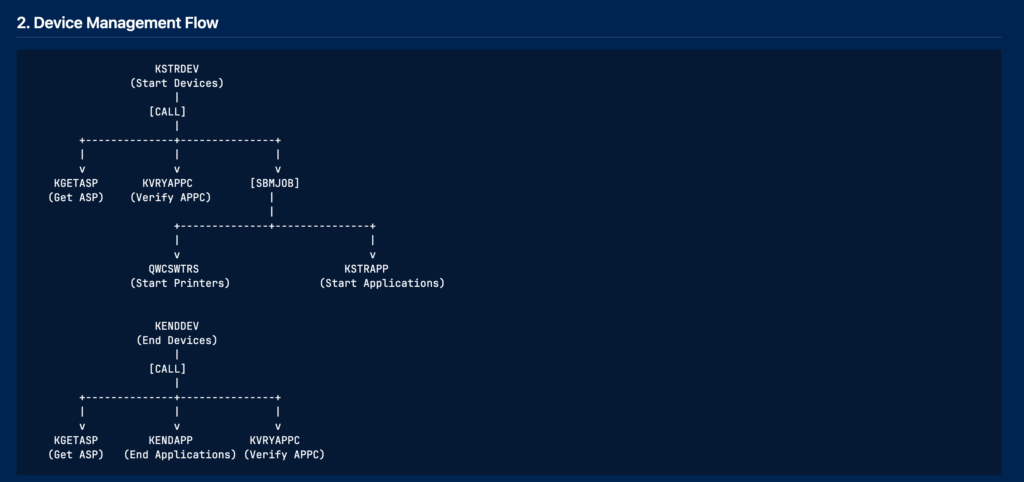
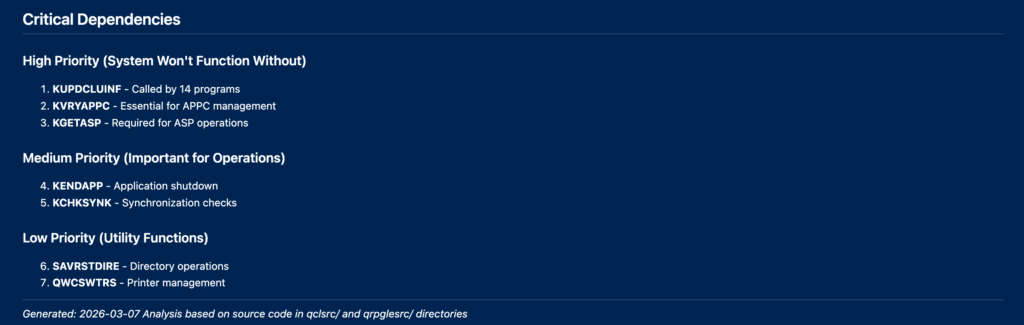
In this case too, the workflow was highlighted with the various planned features, followed by details on the individual stages. Furthermore, as you can see, particular attention was paid to DTAARA in this case. Now let’s ask BOB to generate a dependency report for the various programs. This is the output it generated for me:
As you can see, it was able to identify all the relationships between the various programs and the expected invocation mode, whether internal or external to the project. It also generated statistical information about program calls:
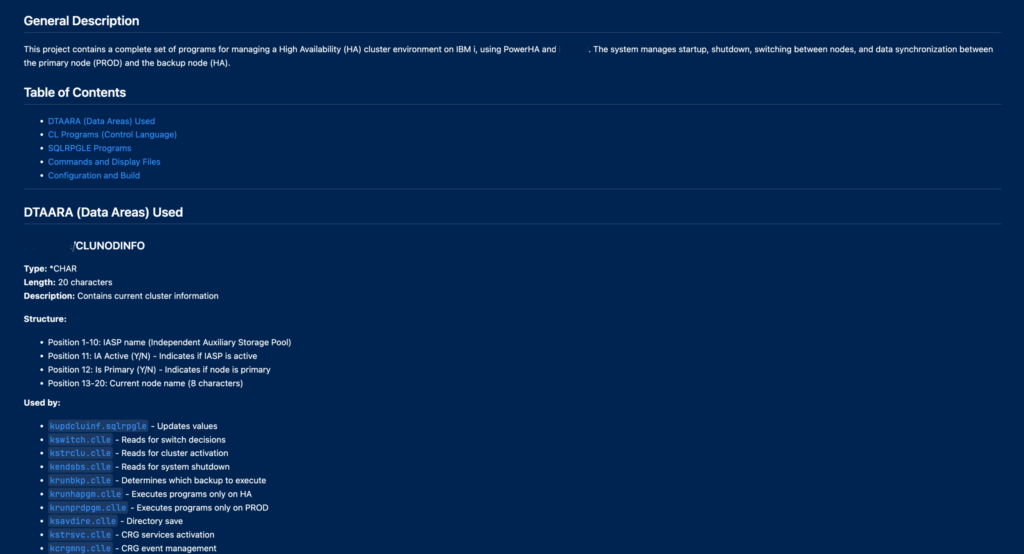
The last point, I’ve asked bob to generate a Readme that list every program inside the project with the features provided, every DTAARA used inside the project with information about the usage:
What I obtained was complete documentation, ranging from comments on individual programs to flowcharts and details such as dtaaras, their values, and dependencies.
I often find myself needing to run several commands in QSH, and I have now found an alternative way to do this compared to the classic bash scripts. Once again, SQL comes to our aid.
Now, using QSH in batch mode is very simple but requires a little attention. In our case, for example, we used two environment variables that can be extremely useful. The first is QIBM_QSH_CMD_OUTPUT. This variable allows you to define where to leave the output of the QSH session. In interactive mode, for example, the default is STDOUT, so when a command is executed in QSH, the panel opens. In our case, when submitting in batch mode, the easiest way is to generate a log file. The second variable, QIBM_QSH_CMD_ESCAPE_MSG, is also extremely useful and allows you to intercept errors that occur during the execution of a command in QSH. Otherwise, it would only generate an informational message in the job log stating that the exit status of the command is not 0.
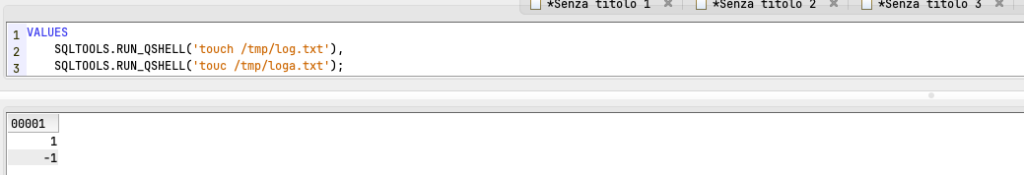
First, I built a scalar function that took the command to be executed as a parameter and returned the result of the execution. The use case is when you need to execute a command that does not return any particular output. Here is an example:
As you can see, the first command works fine with rc 1, the second has an error and returns me -1.
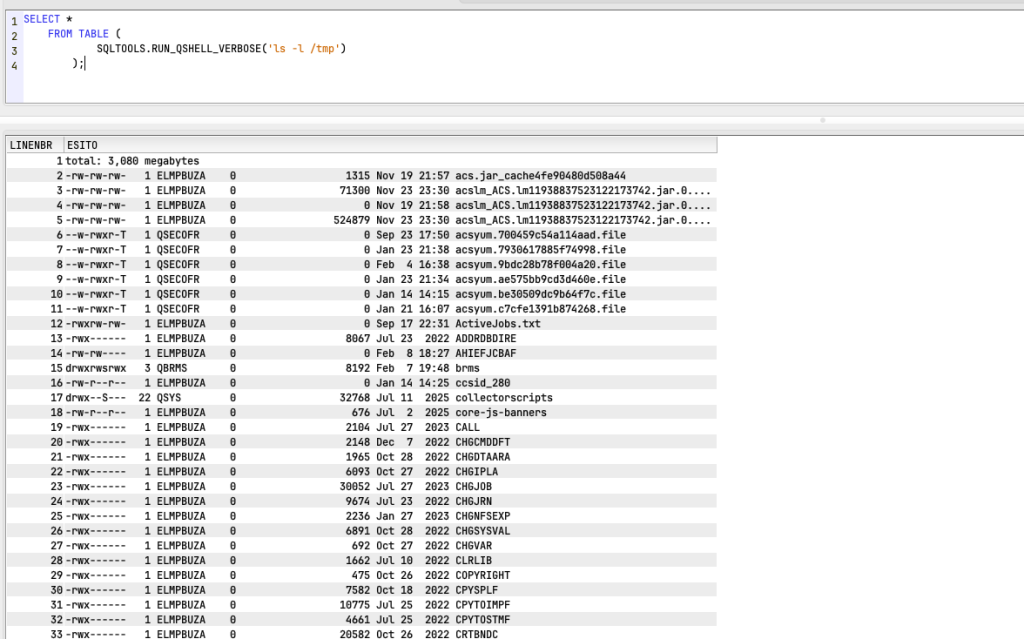
After that, I created a second function, which in this case returns a table. This allows you to return the result of a command if needed. Here is another fairly trivial example with ls -l:
As you can see, in this case returns me the list of objects that are in /tmp directory.
Some implementation notes… with regard to the above comments on environment variables, when the script starts, it checks for the existence of these environment variables. If they exist, it modifies them and then restores them at the end of execution. If they do not exist, it creates them and then removes them. As for the version with table function, in this case the output is generated in a temporary file under /tmp. This temporary file is read and its contents are inserted into a file in QTEMP. The output of the function is the contents of that file in QTEMP. Also note that in order to avoid clutter, the ifs file is deleted once its contents are transferred to QTEMP.
And you, have you ever needed to run a QSH command from SQL, perhaps because it was contained in a table, etc.?
As usual, the source code for the functions is available on my GIST at this link.
During the Christmas holidays, between various lunches with relatives, an outing, and, of course, some rest, I had the opportunity to rework the Code4i FS extension a bit. It was very challenging in that it allowed me to learn a new language, TypeScript, and to learn about new aspects and SQL services of the IBM i operating system that I was completely unaware of before.
For those unfamiliar with it, this extension allows you to use and, in some cases, even manage additional objects beyond those traditionally supported by the standard extension. The aim is to improve the user experience for programmers (but not only them) by providing a single interface from which to work and get feedback, avoiding the need to switch frantically between applications. In addition, it is intended as a tool to help those who are just starting out and therefore have less experience, as the GUI greatly simplifies things.
New supported object types are 20, here you can find a list with the major features:
Data Queue
Send Message: Keyed/non-keyed support, UTF8 format, length validation, key validation
Clear Queue: Removes all messages with confirmation
View: Program info, bound modules with source details, bound service programs with signatures, exported procedures (SRVPGM only), SQL settings, optimization details, activation group
Query Definition
Translate to SQL: Converts Query/400 definitions to SQL format using RTVQMQRY command
View: SQL translation of query definition with proper table notation (LIB.FILE instead of LIB/FILE)
Note: Uses temporary source file and alias for extraction, automatically cleans up temporary objects
I would like to point out that this is not the final version; it is currently being reviewed by the Code4i team as the extension is part of that ecosystem. It is therefore possible that it may undergo further changes. However, it would be interesting for other users to be able to test it now in ALPHA so that any bugs can be checked and corrected, as well as to gather feedback on new features. So, if you want to be a tester, write a comment and I’ll get back to you with instructions.