In today’s article, we will see how it is possible to integrate an MCP server installed directly on IBM i with BOB, and yes, it can be done with very interesting results.
An MCP (Model Context Protocol) server is middleware that allows you to define a set of information that is made visible by the source system (in our case, an IBM i) to an AI agent. As we will see later, it is possible to define your own tools to make available to the agent.
Let’s say that the purpose of this article is not to explain how to deploy an MCP server (however, I remain available if you need a hand). The IBM team has done (or rather is doing) a fantastic job in documenting this open source tool they have created. Here is the link to the GIT repo and documentation. In fact, we will rely on their MCP server, but keep in mind that if you are good at development, you can implement your own.
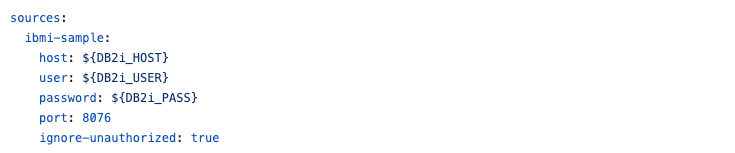
Once the MCP server has been deployed, which can reside either on IBM i or on external systems, the important thing is that there is communication with the Mapepire server on IBM i. Here ohw to define the data source:
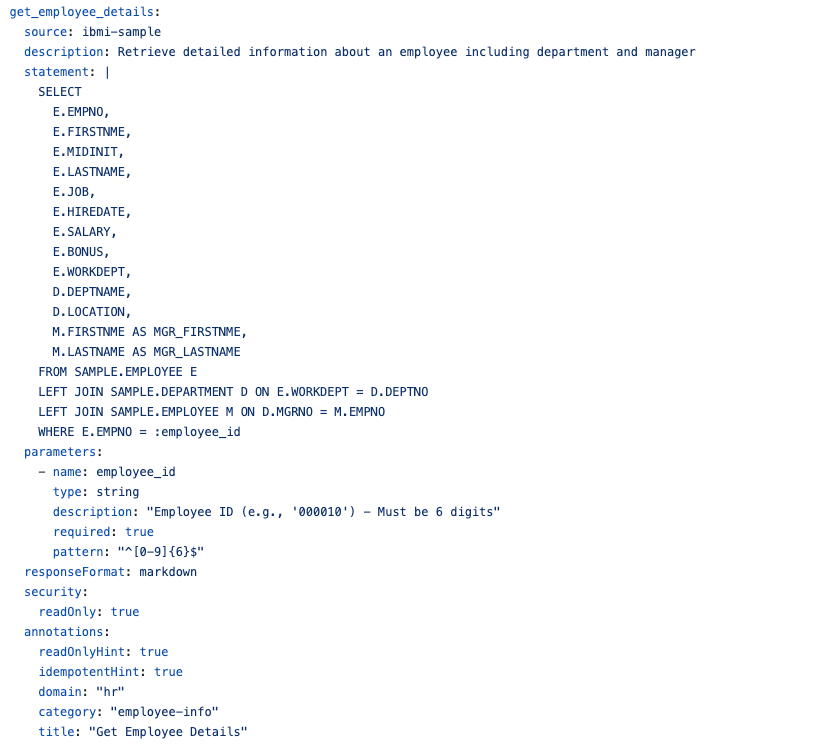
We can then proceed with the creation of some of our own tools. The tools are nothing more than the instrument used by the MCP server to expose the data. In our case, for example, a tool is defined as follows:
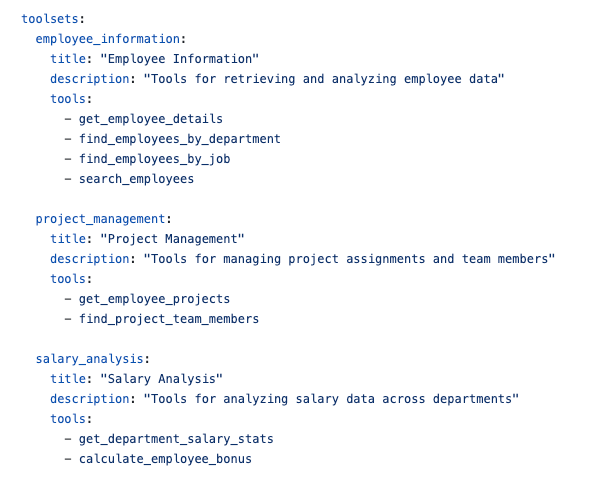
and then the toolsets, a semantic grouping of information:
The example above is taken directly from the GIT repository.
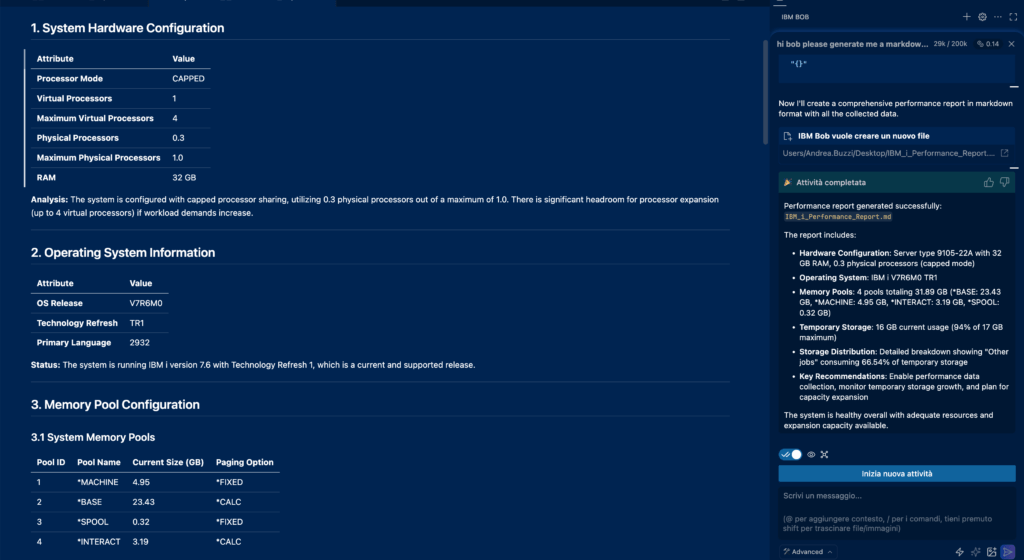
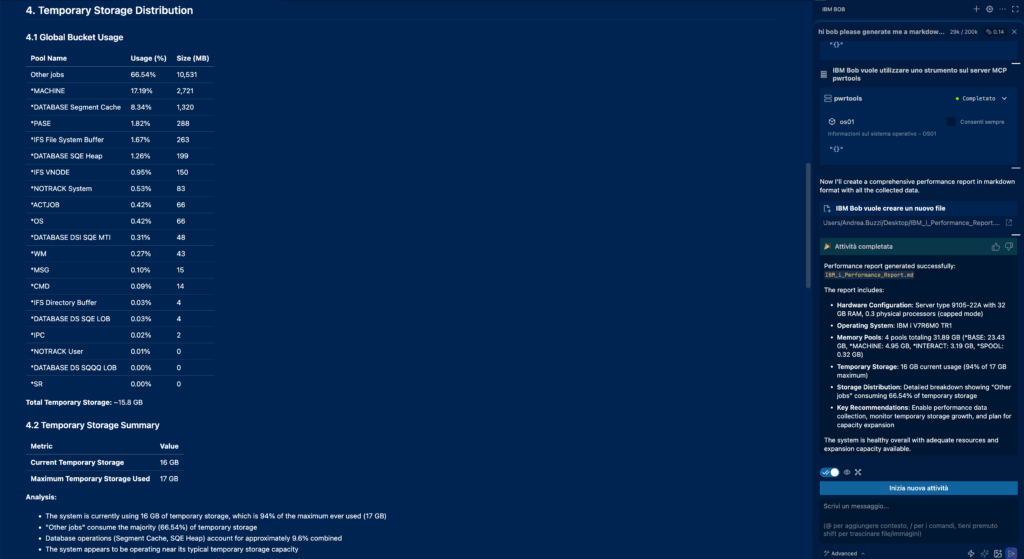
Now you are probably wondering about the added value of this tool… well, an MCP is essential for breaking down certain barriers. For example, thanks to this tool, even someone without specific knowledge of the platform can extract information by asking an AI agent questions in natural language. One example of an AI agent (not the only one) is BOB, and in the example below, I ask it to generate a report in markdown format about the performance of my system:
This is what I got: a comprehensive report on the machine configuration and information on memory pools, as well as an overview of my system’s temporary storage usage. All by asking Bob, “Hi Bob, please generate me a markdown performance report in English for my system.”
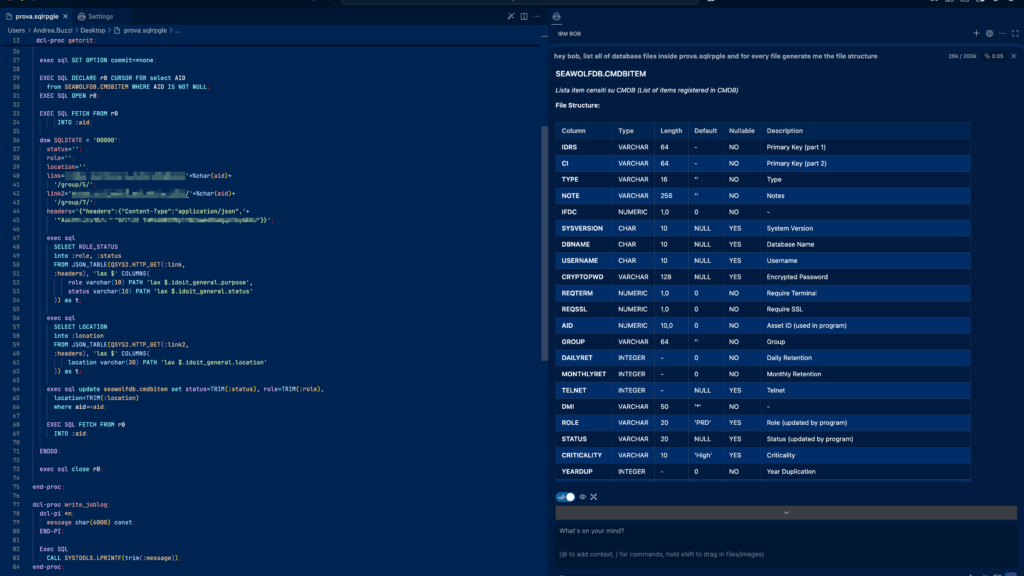
But let’s go further: an MCP server can also support development activities. In this case, we will ask BOB to generate a report on the database files used in a program by generating the file structure:
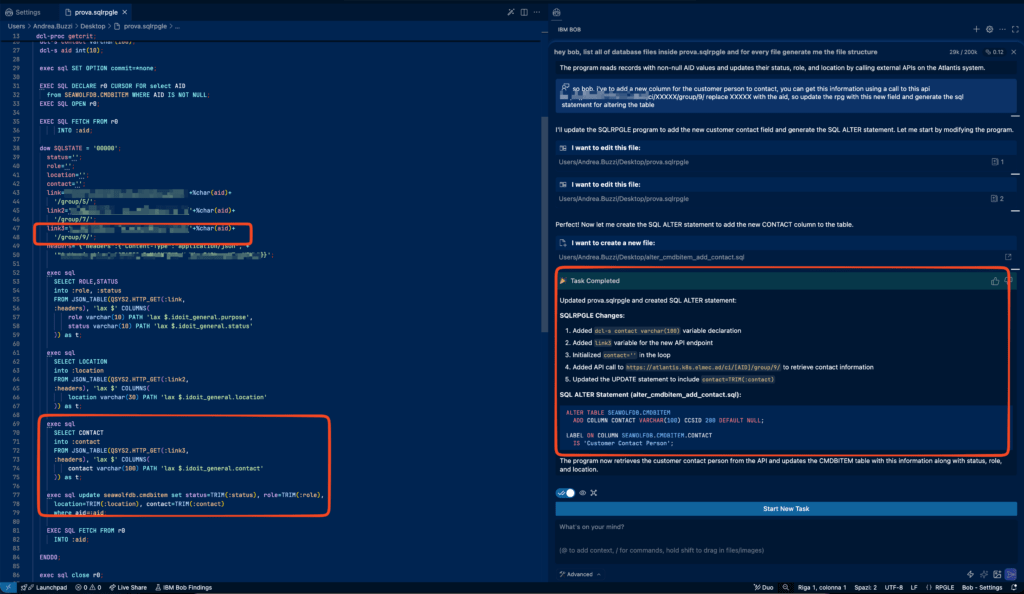
Let’s assume that I need to add a new column that shows me the machine reference, and I also extract that via an API call. I will ask BOB to update the source and generate the statement to modify the table, since MCP cannot (fortunately) perform modifications.
As you can see, he was able to update the RPG source code, taking into account the new field and the fact that an API call was needed to retrieve it. He also provided me with the information I needed to modify the structure of my table.
As you can imagine, this combination of MCP and agent (in my case, BOB) can be a real game changer for everyday activities, from developers to workers to managers, who no longer have to interface with a fixed form to fill out but with an interface that speaks a natural language like us.
A few weeks ago, I wrote an article about BOB in which I talked about my initial experience and how I had used it in Java. Now, some time later and after reaching the $200 ceiling, let’s talk about support for typical IBM i languages, RPG, and CL.
We are still a long way from being able to use it for many IBM i developers, because at the moment BOB is not able to connect to the system and scan the sources contained in classic source files. The situation is different for those like me who have sources on repositories such as Git. In fact, when you have the repo locally, BOB can unleash its full power.
Now, you should already know that in this article we will talk almost exclusively about documentation… this is one of the most requested use cases by various customers, because often the code that a customer has in their hands is poorly documented or not documented at all, there are no indications about flows and interactions, dependencies with objects and the database, etc., so I decided to do an in-depth analysis of this.
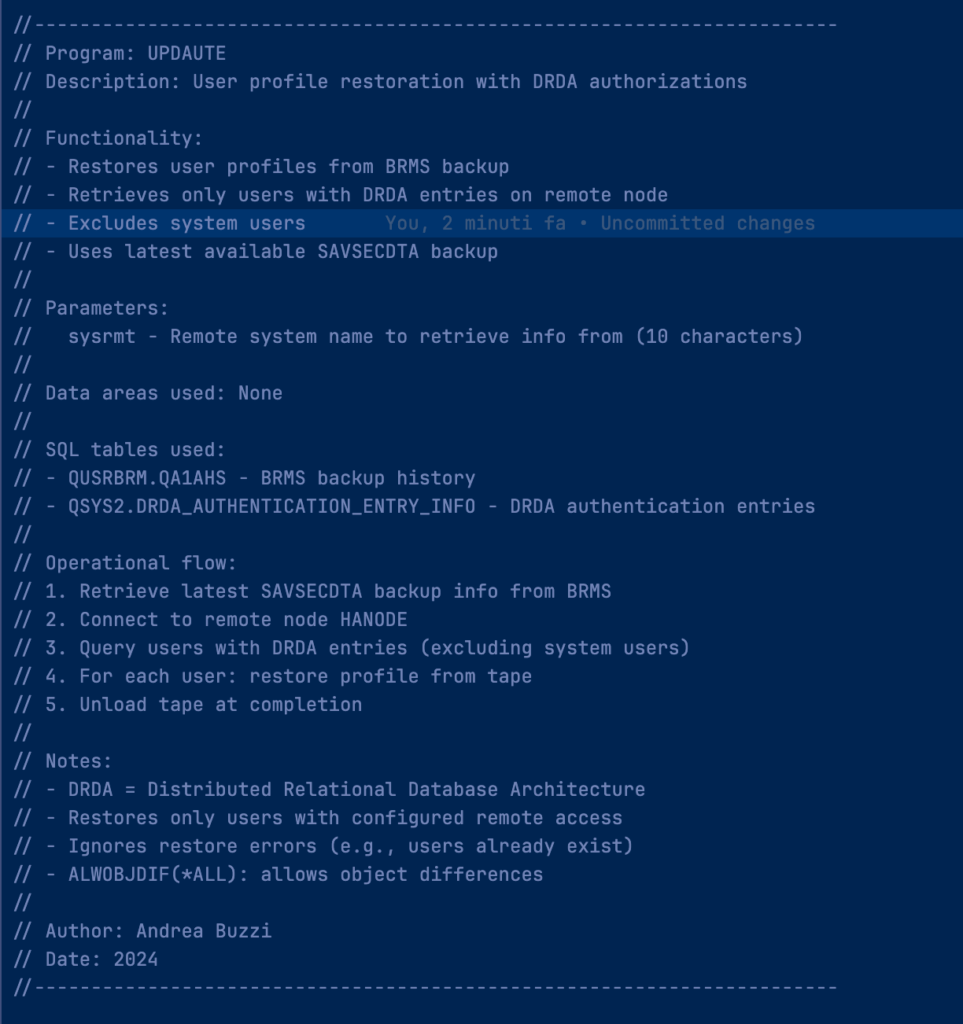
Let’s start with an example project, with about 20 CL programs and 12 RPG programs. Let’s start with the simple stuff and analyze an RPG program, asking it to make various comments on functions, etc.: “Hi bob, genereta english comments about kupdaute” and after few seconds I’ve my comments:
and
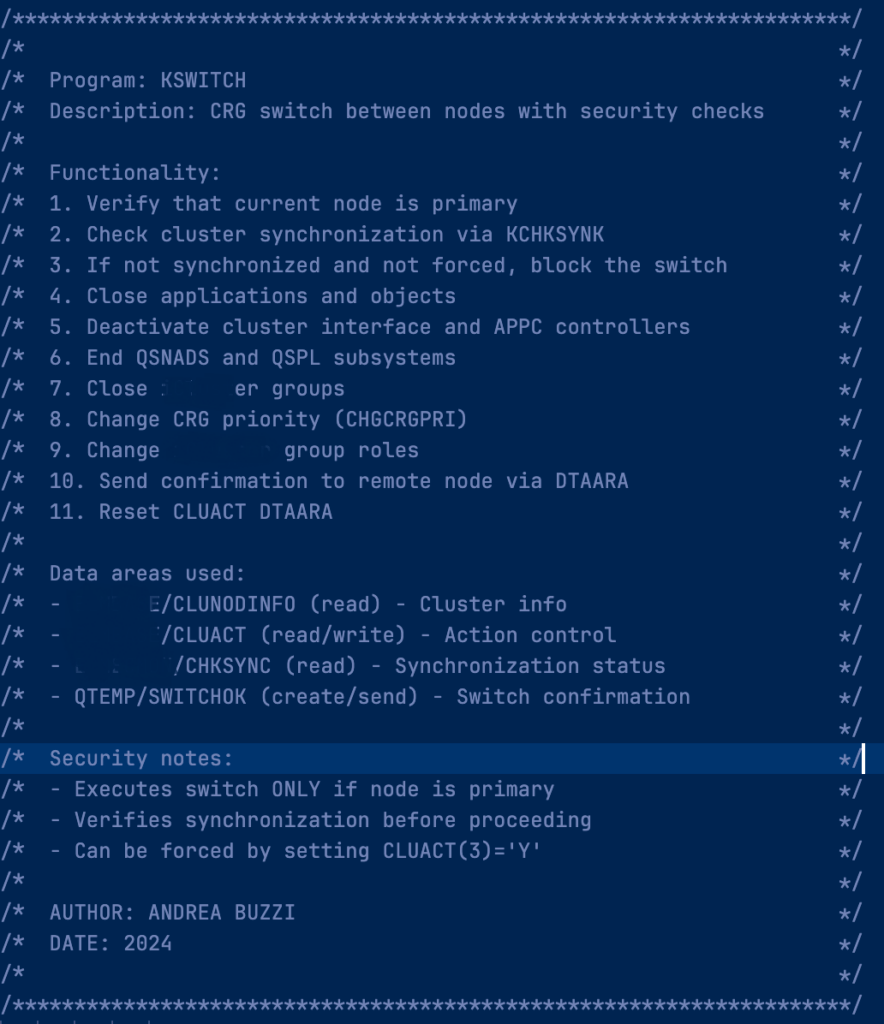
As you can see, it was able to generate comments for both the program itself and the individual operational steps that make up the application procedure, highlighting, for example, the database files that I was going to use. Let’s try now with a CL program:
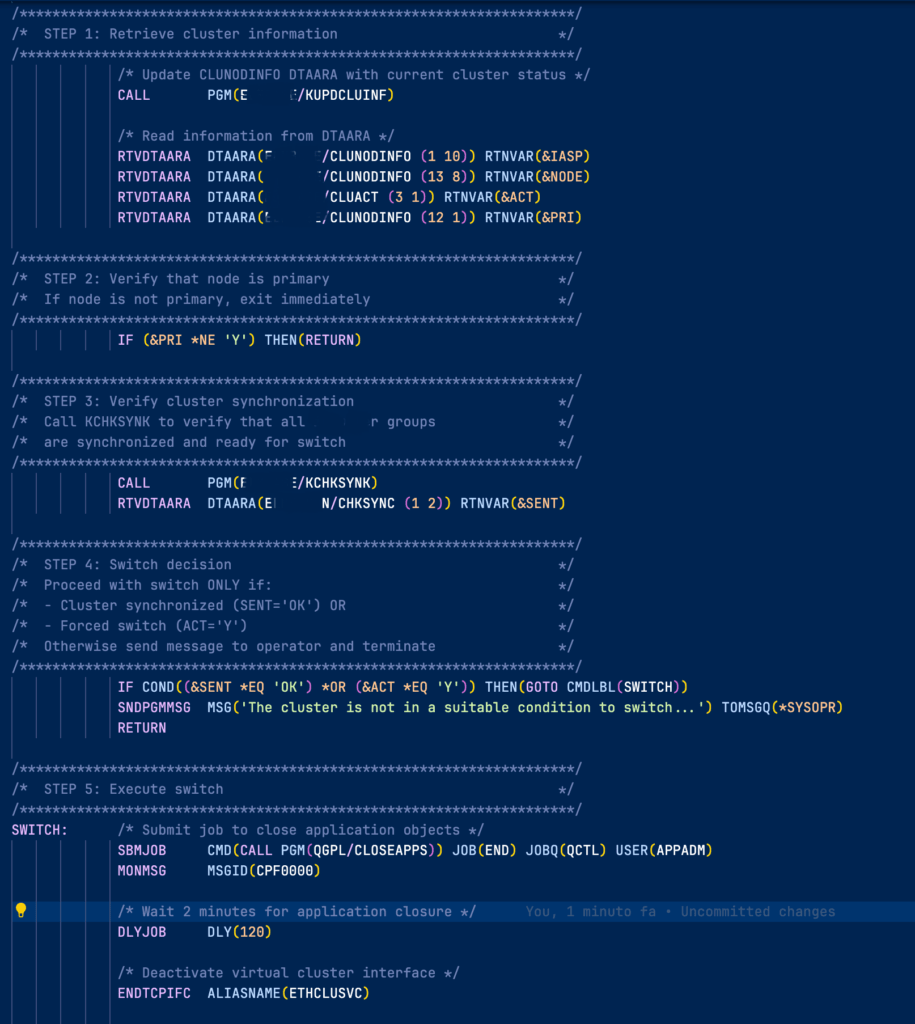
and
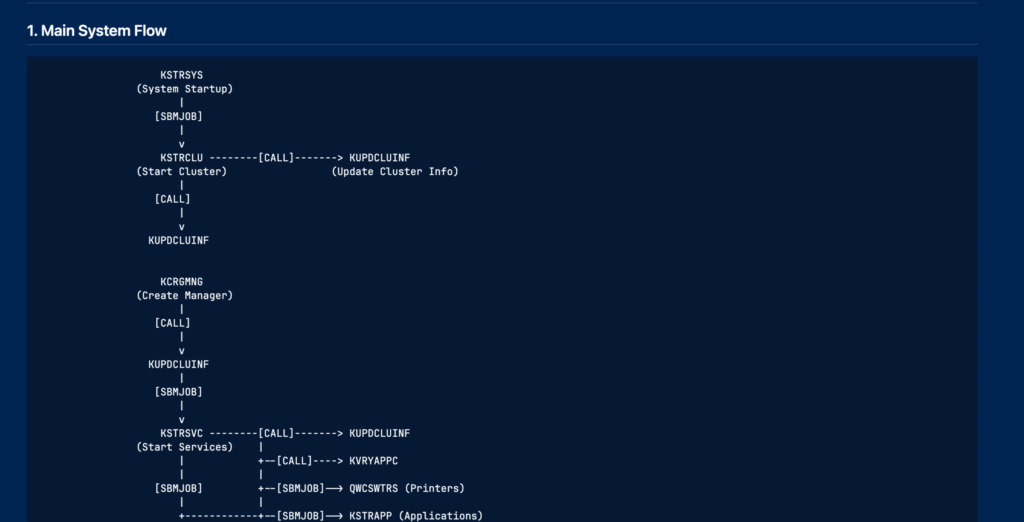
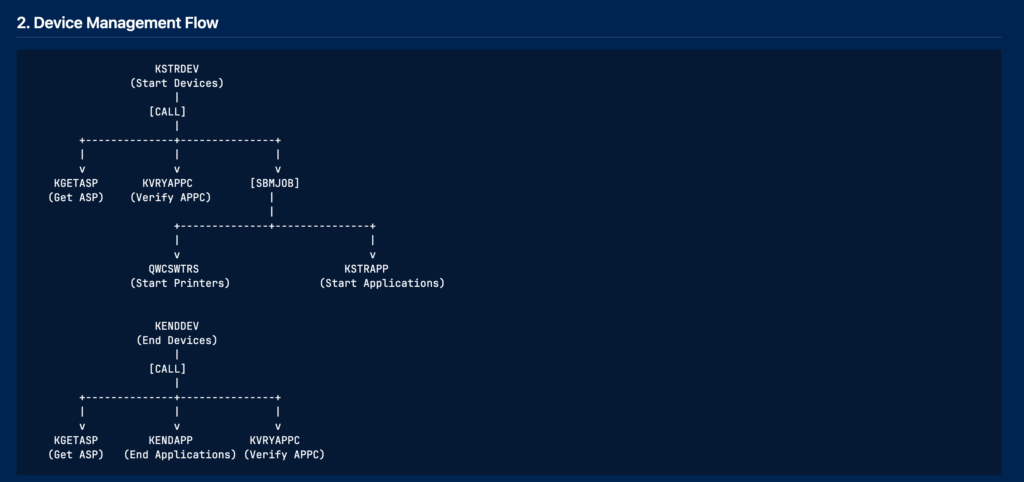
In this case too, the workflow was highlighted with the various planned features, followed by details on the individual stages. Furthermore, as you can see, particular attention was paid to DTAARA in this case. Now let’s ask BOB to generate a dependency report for the various programs. This is the output it generated for me:
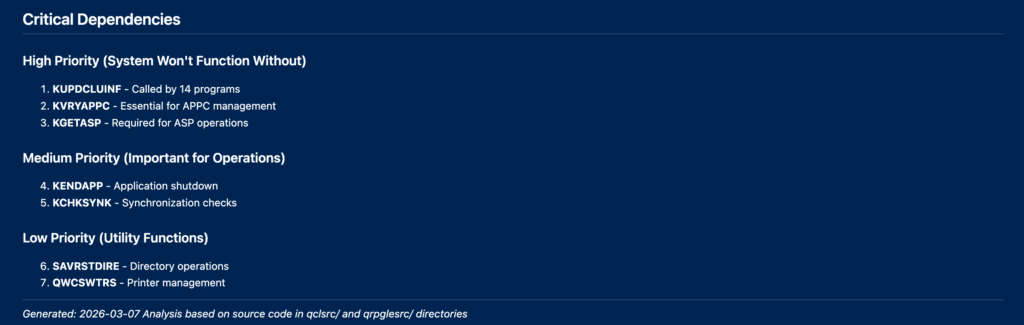
As you can see, it was able to identify all the relationships between the various programs and the expected invocation mode, whether internal or external to the project. It also generated statistical information about program calls:
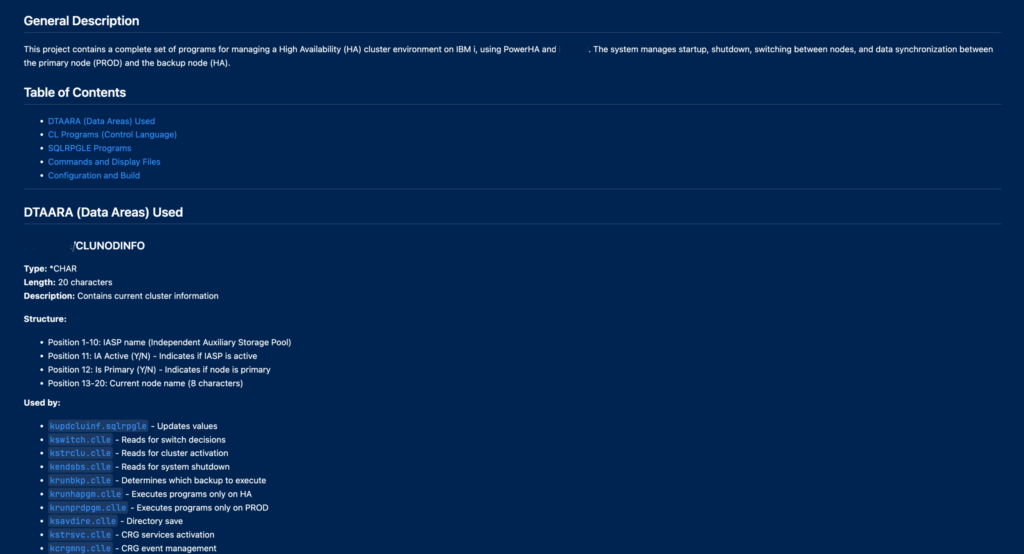
The last point, I’ve asked bob to generate a Readme that list every program inside the project with the features provided, every DTAARA used inside the project with information about the usage:
What I obtained was complete documentation, ranging from comments on individual programs to flowcharts and details such as dtaaras, their values, and dependencies.
The ACS tool is very convenient and rich in features that go beyond simple 5250 emulation. In fact, this tool can be used to perform database management and maintenance operations, transfer IFS data or database files rather than spools. These are some of its functions…
As you can imagine, it is a real Swiss Army knife whose impact is sometimes underestimated. However, there are ways to limit the features available to users.
The AcsConfig.properties file, which is usually located in the root of the ACS installation, allows you to define two different approaches. The first is the historical approach defined with the com.ibm.iaccess.ExcludeComps directive, allows you to disable individual features, but this means that if IBM adds a new feature, you would have to rush to add it to the features to be excluded if you do not want it to be available. The other approach, which is more secure from this point of view, allows you to specify only which features are allowed and is managed by the com.ibm.iaccess.IncludeComps directive, which effectively excludes all features not explicitly included.
In this screenshot, you can see the documentation provided for these expressions. It is important to note that the two options cannot be combined, so you must either proceed with exclusion or inclusion.
Please note that the AcsConfig.properties file is a text file that contains the default settings as well as the features mentioned above. However, it is a file that can be “easily” modified by users, so if you are an administrator and want to secure it, you have two different options for doing so. The first mechanism involves modifying the file’s security attributes by setting it to read-only mode on Windows or 444 mode on Mac or Linux, so that users do not have permission to edit it. Another way is to insert the file into the acsbundle.jar file, which is the file that contains the ACS executable code. A jar file is a compressed archive, so you can use an application such as 7zip or other archive browsers and insert the file into that archive. That way, there will no longer be any text files that are easy for users to edit. However, you need to be careful with ACS updates, because in that case the acsbundle.jar file is overwritten with each update, so the configuration must be reinserted with each update.
Another thing to pay particular attention to is related to installation. If ACS is not installed correctly but only the jar file is executed, these limitations will not apply and there is no way for the IBM i system to block function usage or anything else.
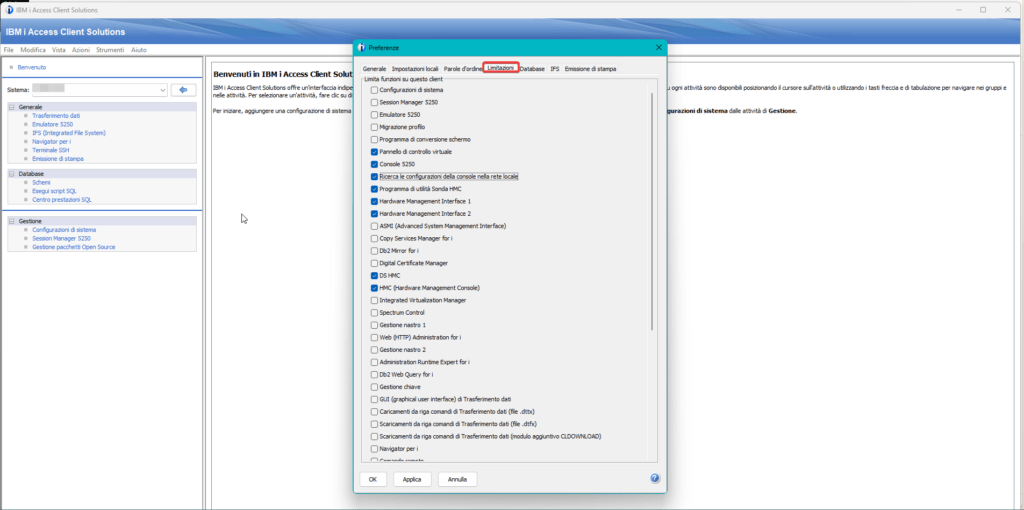
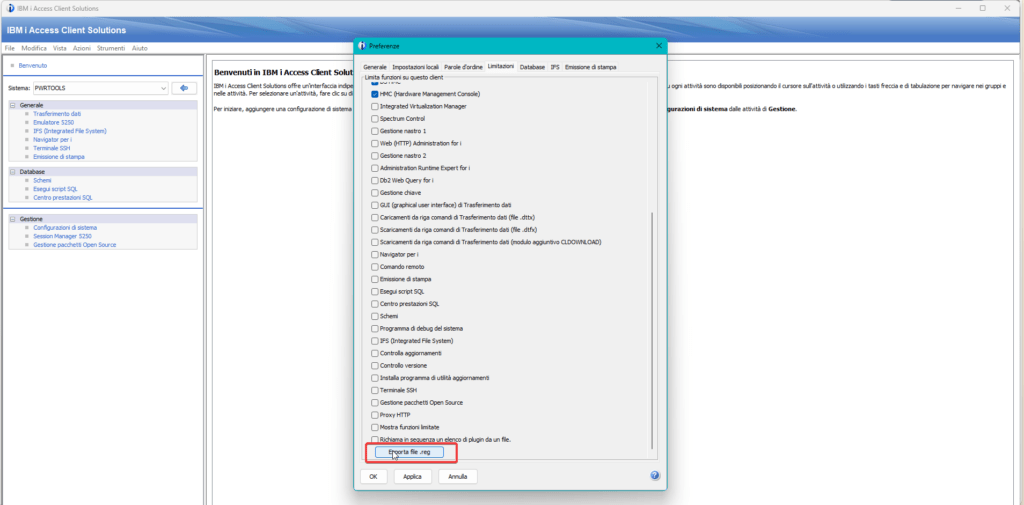
But administrators, don’t worry, because there is an even better way to manage the permissions of this fantastic tool. By opening ACS in administrative mode on Windows or with root privileges on Mac or Linux, a screen like the one below will appear in the preferences, showing all the features provided by ACS. From here, you can define a list of features to exclude, as shown in the screenshot:
In my example, I disabled all HMC-related features on my client. Scrolling down, I see a button that allows me to export the script that lets me modify the system registry to make these changes, because in this case the changes are not defined at the ACS configuration level but at the Windows level. What you can guess is that by distributing this file, you can define policies on Active Directory that allow various user groups to access or not access certain functions of the Access client.
And you, have you ever thought about how to manage these ACS features centrally on your clients?
I often find myself needing to run several commands in QSH, and I have now found an alternative way to do this compared to the classic bash scripts. Once again, SQL comes to our aid.
Now, using QSH in batch mode is very simple but requires a little attention. In our case, for example, we used two environment variables that can be extremely useful. The first is QIBM_QSH_CMD_OUTPUT. This variable allows you to define where to leave the output of the QSH session. In interactive mode, for example, the default is STDOUT, so when a command is executed in QSH, the panel opens. In our case, when submitting in batch mode, the easiest way is to generate a log file. The second variable, QIBM_QSH_CMD_ESCAPE_MSG, is also extremely useful and allows you to intercept errors that occur during the execution of a command in QSH. Otherwise, it would only generate an informational message in the job log stating that the exit status of the command is not 0.
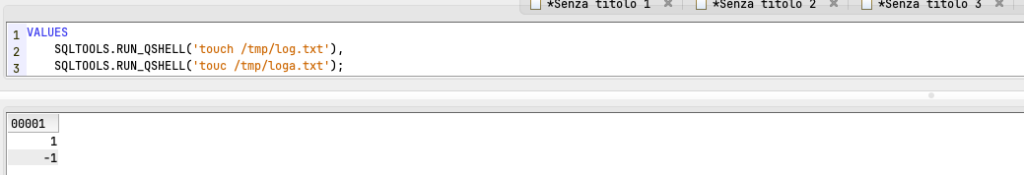
First, I built a scalar function that took the command to be executed as a parameter and returned the result of the execution. The use case is when you need to execute a command that does not return any particular output. Here is an example:
As you can see, the first command works fine with rc 1, the second has an error and returns me -1.
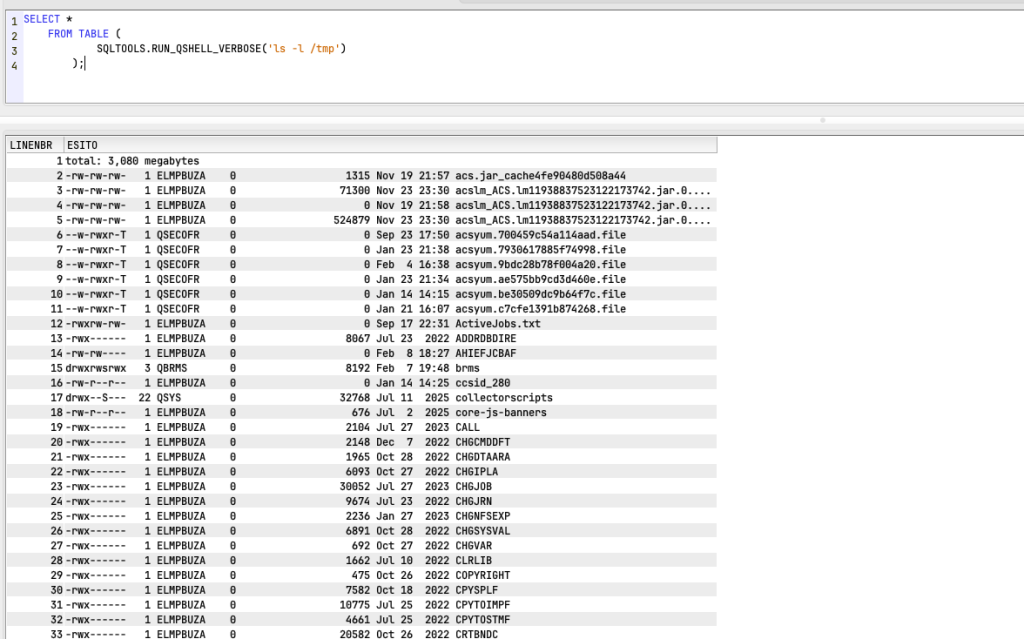
After that, I created a second function, which in this case returns a table. This allows you to return the result of a command if needed. Here is another fairly trivial example with ls -l:
As you can see, in this case returns me the list of objects that are in /tmp directory.
Some implementation notes… with regard to the above comments on environment variables, when the script starts, it checks for the existence of these environment variables. If they exist, it modifies them and then restores them at the end of execution. If they do not exist, it creates them and then removes them. As for the version with table function, in this case the output is generated in a temporary file under /tmp. This temporary file is read and its contents are inserted into a file in QTEMP. The output of the function is the contents of that file in QTEMP. Also note that in order to avoid clutter, the ifs file is deleted once its contents are transferred to QTEMP.
And you, have you ever needed to run a QSH command from SQL, perhaps because it was contained in a table, etc.?
As usual, the source code for the functions is available on my GIST at this link.
This week, a customer opened a ticket complaining that there were too many job logs on their system… this meant that when a user searched for their print job with WRKSPLF, they were inundated with a considerable number of job logs, making it difficult to find the relevant spool.
While I find the spool tool relatively convenient, I often see customers using OUTQs as archives. Let’s be clear: OUTQs are not archives! There are different tools that can perform that function. Moreover, for a sysadmin, the spool is an enemy of performance. Replication tools, for example, replicate one spool at a time. Last year, during the migration of an important customer, we found ourselves having to change the migration method due to poor performance in spool restores (and the customer had about 10 million of them).
Let’s get back to the matter at hand… now, the conditions that can cause a job to leave the log are:
4 0 *SECLVL, and here we need to investigate whether it is the jobd that passes this parameter when starting the job or whether it is modified later with CHGJOB
DSPJOBLOG OUTPUT(*PRINT), again, the configuration specified in the job is overridden by printing it with the execution of that command
SIGNOFF LOG(*LIST), applies only to interactive sessions and ensures that when the interactive session is closed, it leaves the job log
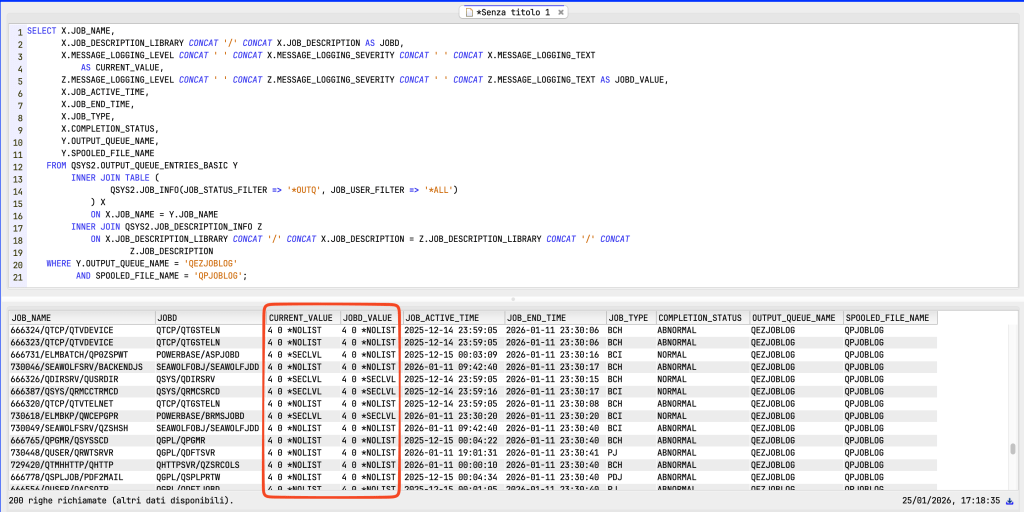
Now, how can I find out the possible cause for the job logs? SQL can be very useful in this case too. In the query example below (you can find the query on my Gist at the following link), I join the OUTPUT_QUEUE_ENTRIES_BASIC view (to extract only jobs with QPJOBLOG files in the QEZJOBLOG print queue) with the JOB_INFO view view (to extract the job execution parameters) and the JOB_DESCRIPTION_INFO view to see the logging parameters in the jobd.
Therefore, if both the jobd and the job have 4 0 *SECLVL as their logging parameter, it means that the job has maintained the settings defined by the jobd. If, on the other hand, the jobd reports a different value but the job maintains 4 0 *SECLVL, then it may mean that the job was submitted with a different parameter or that the job execution parameters were changed with the CHGJOB command. If the job value is also different from 4 0 *SECLVL and the job is a batch job, a DSPJOBLOG OUTPUT(*PRINT) has been performed. If it is interactive, the same reasoning is likely to apply, although it is possible to specify SIGNOFF LOG(*LIST).
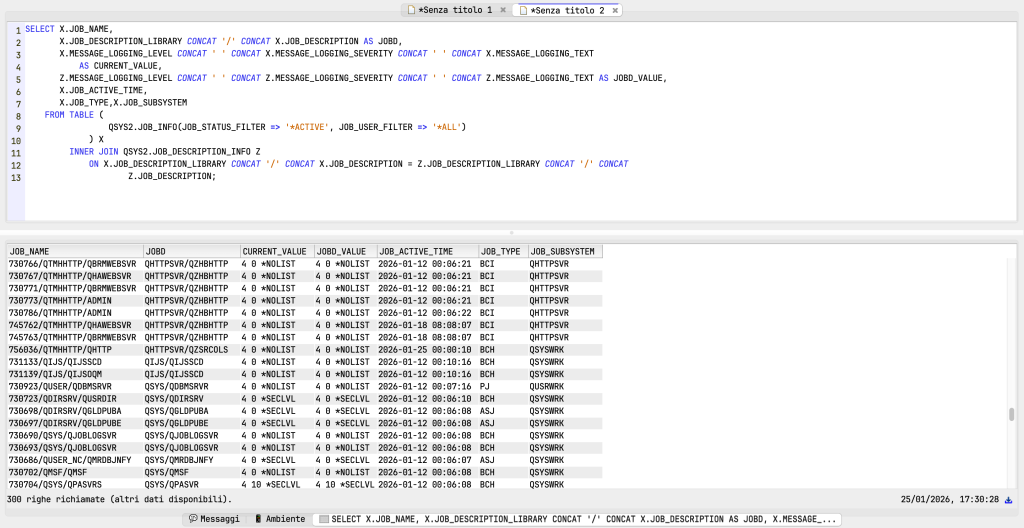
What if I want to analyse active jobs? Well, in this case, the query changes slightly, as there will most likely be no spool…
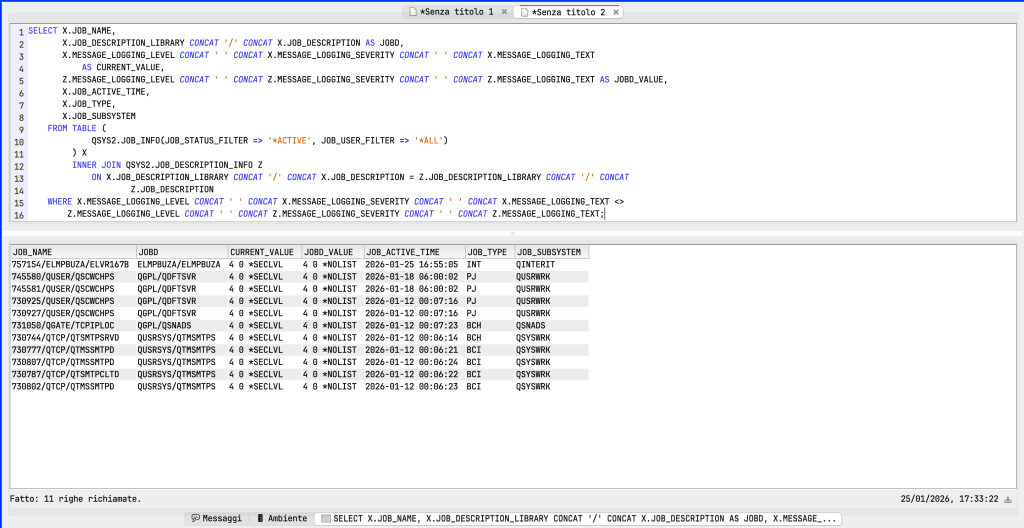
Or, if I want to check only job with defference between current settings and JOBD:
And you, have you ever considered using SQL for this type of analysis? I remind you that all the code is available on my GIST, which you can access at this link: https://gist.github.com/buzzia2001